Guide
Thinking in Systems, Beyond the Framework
Out-of-order responses, duplicate orders, and stale caches: a practical guide to the state, timing, and failure problems hiding behind simple interfaces.

Pranav Gawande
Updated
A user is filtering a list of projects. They click Design, change their mind, and quickly click Engineering. The list shows engineering projects, and then, half a second later, switches back to design projects. The Engineering button is still highlighted. Nothing appears in the console, and every request returned 200 OK.
Every piece of this feature works. The component renders correctly, the API returns the right data for each query, and the database is fine. The bug only exists in how the pieces interact over time.
Knowing React, Next.js, or any other framework tells you how to build each piece. It doesn't tell you which of two correct responses deserves to be on the screen. That's a systems question. This article is about asking those questions on purpose: who owns a piece of data, what happens when events arrive in an unexpected order, what a failure actually means, and how old information can get before it misleads someone.
Follow one action through the whole system
The most useful habit here is also the simplest: pick one user action and trace it from the click all the way to the database and back.
- BrowserForm draftKnows what the user typed
- NetworkRequest in flightMay arrive, fail, or be lost
- APIValidationDecides whether the change is allowed
- DatabaseSaved valueThe source of truth
Caches, CDNs, other tabs
Copies that may still show the old value
Take saving a profile. The form holds what the user typed. The request carries it across the network. The API checks it and writes it to the database. Meanwhile, a cache, a CDN, or another browser tab may still be holding the old value. Each of these places knows something different at any given moment, and that's normal. Bugs appear when the interface treats them as if they all knew the same thing.
Tracing an action also exposes vague words. When the button changes to "Saved", what exactly happened? Was the request sent? Did the server accept it? Did the database commit it? Can other people see it yet? Those are four different moments, and some of them can happen without the others. A good interface picks one meaning for "Saved" and waits for that moment before saying it.
Every piece of data needs an owner
For each value on the screen, ask who owns it: which place has the authority to say what it is right now.
The database owns the saved display name. The form owns the draft the user is typing. Those are two different values, and both are legitimate. Trouble starts when a component copies server data into local state and then treats the copy as the truth:
tsx
function ProfileForm({ user }: { user: { name: string } }) {
  // useState reads user.name once, on the first render.
  // If `user` is refetched later, `name` keeps the old value.
  const [name, setName] = useState(user.name);

  return <input value={name} onChange={(e) => setName(e.target.value)} />;
}
This is fine as long as everyone understands that name is a draft. It becomes a bug when another part of the interface assumes name still matches the server. The fix is a decision rather than a library: the draft is explicitly a draft, the saved value comes from the server, and the code compares the two on purpose, for example to show an "unsaved changes" warning, instead of letting them quietly drift apart.
Time is an input
Back to the filter. Here's what happened, laid out on a timeline.
Network requests aren't guaranteed to finish in the order they started. The Design query might hit a slower database index, take a longer route, or wait behind another request. If the code displays whichever response arrived most recently, it displays the wrong one.
What the interface actually needs is narrower: show the response that matches the user's current selection. One framework-free way to enforce that is to number each request and ignore any result that isn't from the latest one:
ts
let latestRequestId = 0;

async function showProjects(category: string) {
  const requestId = ++latestRequestId;
  const response = await fetch(`/api/projects?category=${encodeURIComponent(category)}`);
  const projects = await response.json();

  // A newer request started while this one was in flight. Drop the result.
  if (requestId !== latestRequestId) return;
  renderProjects(projects);
}
In React, an effect's cleanup function does the same job. This is the pattern React's documentation recommends, with an AbortController added so the browser can also stop the outdated request:
tsx
useEffect(() => {
  const controller = new AbortController();
  let ignore = false;

  fetch(`/api/projects?category=${encodeURIComponent(category)}`, { signal: controller.signal })
    .then((response) => {
      if (!response.ok) throw new Error(`Request failed with ${response.status}`);
      return response.json();
    })
    .then((data) => {
      if (!ignore) setProjects(data);
    })
    .catch((error) => {
      if (!ignore) setError(error);
    });

  return () => {
    ignore = true;
    controller.abort();
  };
}, [category]);
Each run of the effect gets its own ignore variable. When category changes, React runs the previous run's cleanup first, so the old request's flag flips to true and its result is thrown away whenever it arrives. Aborting saves bandwidth, but the flag is what guarantees correctness, because not every asynchronous step after a fetch can be cancelled. Data-fetching libraries such as TanStack Query solve this for you by tying each result to the query that produced it, but it helps to know which problem they're solving.
The same issue shows up in search-as-you-type, autocomplete, tab switching, and anything that refreshes in the background. Once time is involved, "the latest response" and "the response to the latest request" are two different things.
A failed request is not always a failed operation
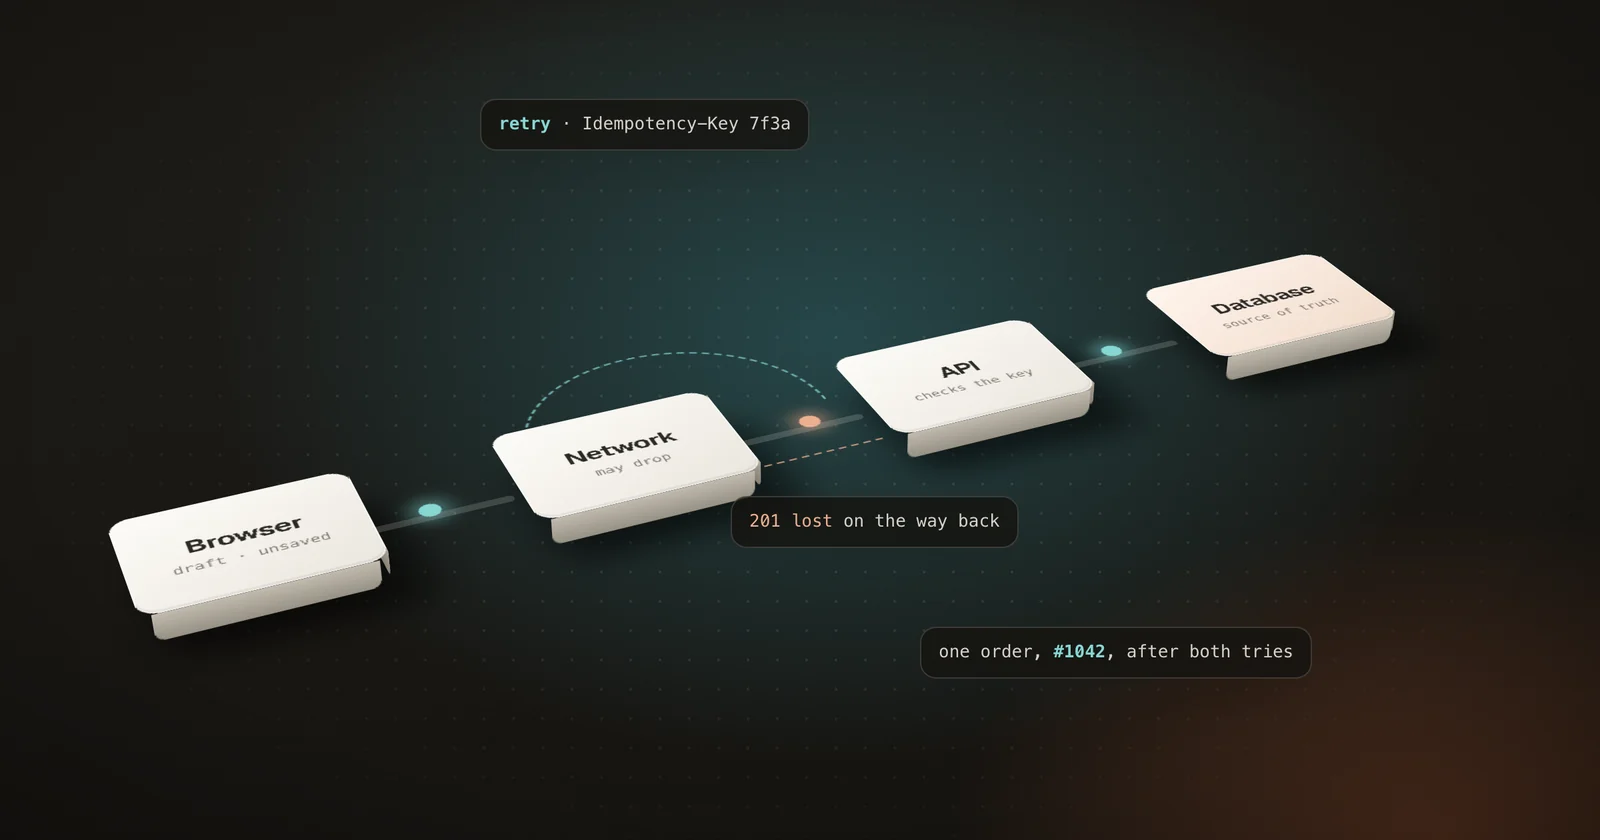
Here's a more expensive version of the same problem. A user taps Place order. The server writes the order to the database and sends back a success response. On the way back, the user's phone switches from Wi-Fi to mobile data and the connection drops.
From the browser's point of view, the request failed. From the database's point of view, the order exists. If the interface says "Something went wrong, please try again", the user taps again, and now there are two orders.
Some operations are safe to repeat. Fetching a list twice gives you the same list. HTTP defines methods like GET, PUT, and DELETE as idempotent, meaning that sending the same request twice has the same effect as sending it once. POST, which usually creates something new, is not idempotent.
The standard fix is an idempotency key. The client creates a unique ID once per user intent, for example when the checkout page opens, and sends that same ID with every attempt to place the order. The server remembers which keys it has already handled. A retry with a known key gets the original result back instead of doing the work again.
Stripe's API is a well-documented example. It saves the status code and body of the first request made with a key, returns that saved response to any retry, and rejects a reused key whose parameters don't match the original. An IETF draft standardizes the Idempotency-Key header itself.
The tricky part on the server is concurrency: two retries can arrive at the same moment, and both can check "have I seen this key?" before either has saved it. Instead of checking in application code, let the database enforce uniqueness. Here's a sketch with PostgreSQL:
sql
create table orders (
  id              uuid primary key default gen_random_uuid(),
  idempotency_key text not null unique,
  customer_id     uuid not null,
  total_cents     integer not null,
  created_at      timestamptz not null default now()
);
ts
// app/api/orders/route.ts, where `db` is a node-postgres Pool.
// A real handler would also authenticate the user and validate the body.
export async function POST(request: Request) {
  const key = request.headers.get("Idempotency-Key");
  if (!key) {
    return Response.json({ error: "Idempotency-Key header is required" }, { status: 400 });
  }
  const { customerId, totalCents } = await request.json();

  // The unique constraint means only one insert per key can ever succeed,
  // even when two retries arrive at the same moment.
  await db.query(
    `insert into orders (idempotency_key, customer_id, total_cents)
     values ($1, $2, $3)
     on conflict (idempotency_key) do nothing`,
    [key, customerId, totalCents],
  );

  const { rows } = await db.query(
    "select id, customer_id, total_cents from orders where idempotency_key = $1",
    [key],
  );
  const order = rows[0];
  if (order.customer_id !== customerId || order.total_cents !== totalCents) {
    return Response.json({ error: "This key was already used for a different order" }, { status: 422 });
  }
  return Response.json({ orderId: order.id }, { status: 201 });
}
On the client, the key has to be created once per intent, not once per tap:
tsx
// One key per checkout. Every retry of this order reuses it.
const [idempotencyKey] = useState(() => crypto.randomUUID());
The interface needs an opinion about uncertainty, too. When the response is lost, the honest message isn't "Order failed". It's "We couldn't confirm your order", followed by a status check or a safe retry with the same key. Not knowing is a real state, and it deserves its own screen.
Saving
Placing your order…
Request sent with key 7f3a
Unknown
We couldn’t confirm your order
Checking with the server. There’s no need to tap again.
Saved
Order #1042 placed
One order, even after the retry.
Automatic retries need limits as well. They should only apply to operations that are safe to repeat, stop after a few attempts, and wait a little longer each time, with some randomness mixed in so thousands of clients don't retry in lockstep right after an outage. AWS's article on timeouts, retries, and backoff with jitter explains why that randomness matters.
Freshness: how old can this data be?
Caches make applications feel fast. They also mean some of the data on screen is a copy, and copies get old.
How old is acceptable depends on what the data is for. A blog post can be an hour old without anyone noticing. A price can be a few minutes old if checkout recalculates it. The number of seats left on a flight can come from a cache while someone browses, but the purchase itself must check the database, because that's the moment where a stale number costs someone money.
HTTP gives you vocabulary for this. A response sent with this header:
text
Cache-Control: max-age=60, stale-while-revalidate=300is fresh for 60 seconds. For the next 300 seconds, a cache may keep serving the old copy while it fetches a new one in the background. RFC 5861 defines that stale-while-revalidate behavior. Trading a little correctness for speed is exactly right for some data and dangerously wrong for other data.
The interface can help. "Updated 2 minutes ago" next to a number tells people how far to trust it. If a background refresh fails, keeping the last good value while clearly marking it as out of date is usually better than replacing it with an error, and much better than quietly presenting it as live.
Write the states down
Many of the bugs in this article come from states that nobody wrote down. A save button driven by three booleans, isLoading, isError, and isSuccess, can technically be loading and successful at the same time, and it has no way to express "we don't know".
It helps to list the states explicitly, along with the events that move the interface between them.
In TypeScript, a discriminated union turns that diagram into a type. Because each state is a separate object shape, impossible combinations can't be represented, and TypeScript can check that a switch over status handles every case:
ts
type SaveState =
  | { status: "idle" }
  | { status: "saving"; idempotencyKey: string }
  | { status: "saved"; savedAt: Date }
  | { status: "failed"; message: string }        // the server said no
  | { status: "unknown"; idempotencyKey: string }; // no answer arrived
The unknown state is the important one. It keeps the idempotency key, so the code can check on the operation or retry it safely, and the interface can say something true: "We couldn't confirm your changes were saved. Checking now."
Test the timing, not just the happy path
A feature that works when everything is fast and reliable has only been tested under the least interesting conditions. A handful of scenarios cover most of the risk:
- An older response arrives after a newer one.
- The server completes a write, but the response never arrives.
- The user double-clicks a submit button.
- The page reloads while there are unsaved changes.
- The connection drops while the screen is showing live data.
You don't need special tools for most of these. Browser developer tools can throttle the network or switch it off, and a test server can delay specific responses to force them out of order. For each scenario, decide in advance what the user should see, then check that they see it.
Where the framework fits
None of this makes frameworks less important. React's effect cleanup, TanStack Query's query keys, Next.js's caching controls, and PostgreSQL's unique constraints are the tools that carry out these decisions. But a framework can't decide what "saved" means in your product, how old a price is allowed to be, or what to tell someone when the network goes quiet. Those are engineering decisions, and the code has to preserve them.
The next time a feature works in the demo but feels fragile, trace one action and ask four questions. Who owns this data? What happens if responses arrive out of order? What happens if a response never arrives? How old can this information be before it misleads someone? Answering them turns most "random" bugs into predictable ones.
For a concrete example of cancellation and cleanup in a browser app, the FreePDF case study shows how a PDF tool releases memory and workers when an operation fails or the user leaves. And if you're deciding how much of this belongs in a first release, Shipping Faster Starts with a Smaller Promise is about exactly that.